Resource Library : EBOOK
BIRD-Interact Benchmark Results: Methodology and Analysis
Concrete numbers on how AI handles real enterprise data, with AtScale and without it, and what it takes to get from 93% accuracy to 100%.
BIRD-Interact is an open-source benchmark of 600 real business questions asked of 22 messy databases. It holds back the documentation that says which columns to use, and a plausible-looking number scores zero. On the 317 questions that have a right answer, Claude Sonnet 5 got 46% right on its own. With a semantic layer AtScale generated automatically, it got 93%. This 25-page ebook explains how the benchmark works and how six models scored. It also walks through the 23 questions AtScale still missed and the fixes that close the gap to 100%.
What you’ll learn:
- How BIRD-Interact mimics real-world conditions, including how it pushes back on AI the way a colleague would, plus eight real questions and where each one goes wrong.
- How six models scored on all 600 tasks with AtScale and without it, how that compares with the public leaderboard, and why 93 of the questions have no right answer.
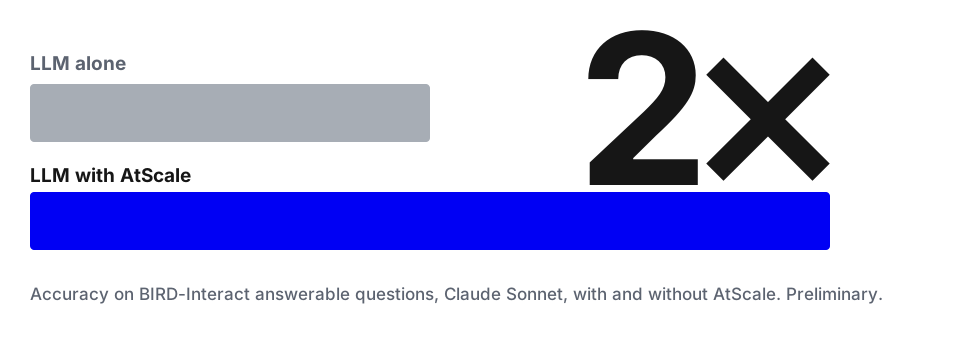
- Results on the 317 answerable questions: 46% with no semantic layer, 93% with one that AtScale generated automatically.
- The four failure modes between AI and 100% accuracy, and how the AtScale AI Accuracy Flywheel addresses each one.
- Five misses from the run, the fix for each one, and the path to 100% AI accuracy.
What’s inside the eBook
Section one: BIRD-Interact, explained
- How BIRD-Interact works
- Four ways BIRD-Interact mimics real-world conditions
- Eight real questions, and where each one goes wrong
- The public BIRD-Interact leaderboard
Section two: AtScale’s benchmark results
- BIRD-Interact with an auto-generated semantic model
- All LLM results, with and without AtScale
- Results on answerable questions
Section three: The pursuit of 100% AI accuracy
- Four failure modes that stand in the way
- The AtScale AI Accuracy Flywheel
- Five misses, five fixes
- The path to 100% AI accuracy
Appendix A has the full numbers. Appendix B covers how every run was configured.
On questions with a right answer, AI alone got 46%. AtScale got 93%.
BIRD-Interact asks business questions of real, dirty databases and holds back the documentation that says which columns to use. A plausible number scores zero.
- 46%: Claude Sonnet 5 with no semantic layer, on the 317 questions that have a right answer
- 93%: The same model with a semantic layer AtScale generated automatically
- 100%: The goal. The AI Accuracy Flywheel, with analysts and data engineers, closes the last 23 misses.
BIRD-Interact stress mode, 317 answerable questions, corrected harness. See atscale.com/bird.
The AtScale AI Accuracy Flywheel
Each step feeds the next, so accuracy only moves one way.
- Semantic modeling (AtScale CoModel): Codifies what the business means. Arrives this fall.
- Prompt disambiguation (AtScale Ava): Asks for clarification when a question is ambiguous instead of guessing. Available today.
- AI metric computation (AtScale ACE): Computes each answer from the certified definition, covering multi-pass calculations, aggregations, time series and semantic memory. Available today.
- Accuracy attestation (AtScale Canary): Tests the result and turns every caught error into a permanent test case. Measure, assess, fix, remember, repeat. Arrives this fall.
About the authors
Dave Mariani, CTO and Founder; Jay Schuren, President; and Mark Palmer, CSMO.
Frequently asked questions
What is the BIRD-Interact benchmark?
BIRD-Interact is an open-source benchmark of 600 real business questions asked of 22 messy databases. It holds back the documentation that says which columns to use, and it scores a plausible but wrong number as zero.
How accurate is AI on BIRD-Interact business questions?
On the 317 questions that have a right answer, Claude Sonnet 5 got 46% right with no semantic layer. With a semantic layer AtScale generated automatically, the same model got 93%.
Why do some BIRD-Interact questions have no right answer?
BIRD-Interact includes questions that can’t be answered correctly as asked, to test whether AI recognizes ambiguity instead of guessing. The ebook explains why 93 of the questions fall into this category.
What is the AtScale AI Accuracy Flywheel?
A four-step cycle for raising AI accuracy: semantic modeling with AtScale CoModel, prompt disambiguation with AtScale Ava, AI metric computation with AtScale ACE, and accuracy attestation with AtScale Canary. Each caught error becomes a permanent test case.