What is BIRD-Interact?
BIRD-Interact is an independent benchmark that tests how well AI systems complete database tasks through conversation. It evaluates whether a system can clarify a vague request, explore the database schema, write correct SQL, and handle a follow-up question.
The full benchmark contains 600 tasks across 22 PostgreSQL databases. Of the 600, 410 tasks are business questions and 190 are management operations, including creating tables, updating records, and deleting data. Executable tests check whether the SQL produces the intended results or database changes.
It was built by the BIRD Team and Google Cloud, and the benchmark paper was published at ICLR 2026.
BIRD vs. BIRD-Interact
The original BIRD benchmark evaluates text-to-SQL: how well a system translates a question into a correct database query. Its tasks require understanding database values and using supplied external knowledge, such as domain definitions, to interpret the request.
BIRD-Interact adds a dynamic exchange. The initial request may be ambiguous, and relevant knowledge may be missing, so the system has to work out what to ask and where to look. It can clarify the request, explore database information, and correct unsuccessful SQL. Once the first task succeeds, a follow-up tests whether it can carry that understanding forward. Tasks also extend beyond reading data to creating tables, updating records, and deleting data.
Why does BIRD-Interact test conversation?
“Which customers are at risk?”
The question sounds straightforward, but it leaves several decisions open. What counts as “at risk”: a high churn probability, no recent orders, or an unresolved support issue? Which window matters: this quarter or the trailing twelve months? And which customers should be included?
A model may choose an interpretation and return a convincing result. The query runs. The answer still misses what the person meant.
Some missing context may be written down in schema descriptions or business documentation. A capable system can look it up. When the available information does not settle the question, the system needs to ask the user.
BIRD-Interact deliberately introduces ambiguity into requests and gaps in the available knowledge. A simulated user provides clarification, allowing the benchmark to test whether the system can gather the information it needs and complete the task correctly.
How does a BIRD-Interact task work?
BIRD-Interact pairs the AI system being evaluated with a simulated user powered by another language model, such as GPT-4o or Haiku 4.5. The system works with a database and supporting documentation, while the simulated user presents requests and answers clarification questions using the benchmark’s annotated task information. Executable tests check the submitted SQL; once the phase 1 task succeeds, the simulated user delivers a follow-up. This setup allows the benchmark to evaluate conversations without a person conducting each one.
Consider a task from the benchmark: count how many accounts fall into each “danger zone” based on their attempts to evade detection.
1. Receive the request.
The wording leaves two key things undefined. First, it doesn’t define what it means to evade detection. Second, it doesn’t define a danger zone or how many there are.
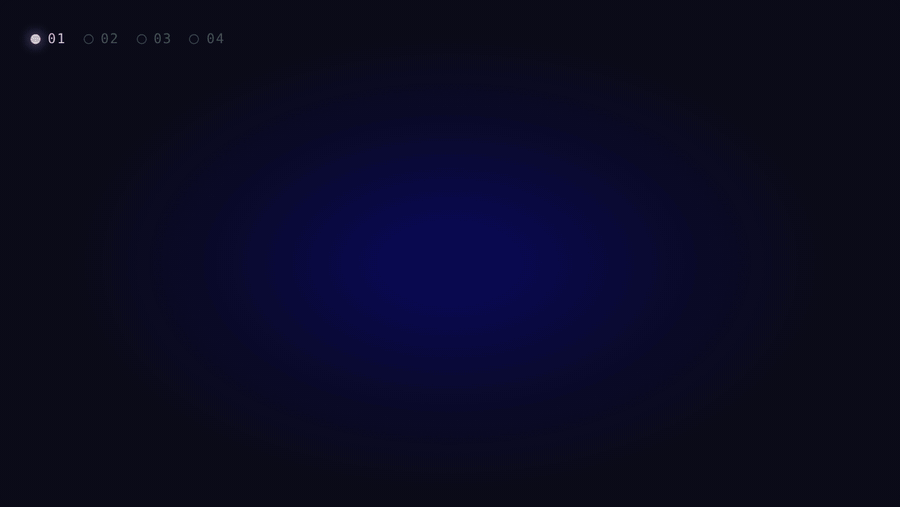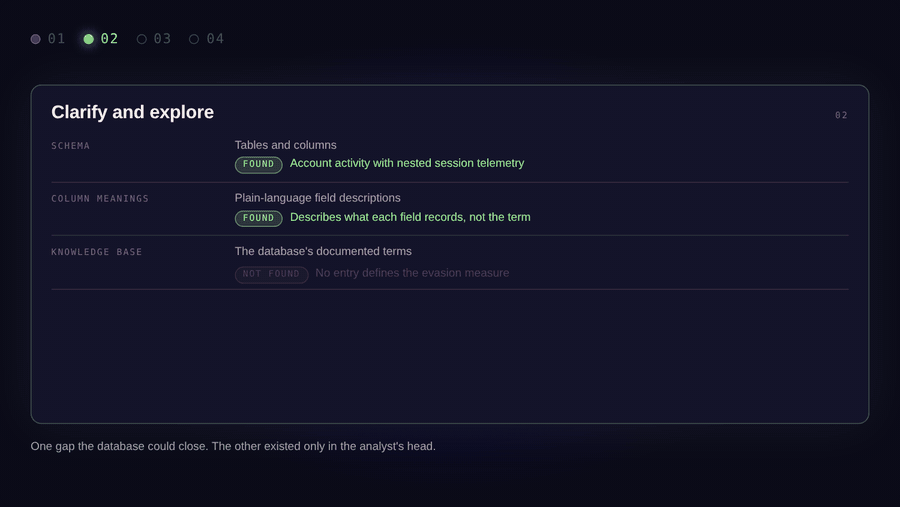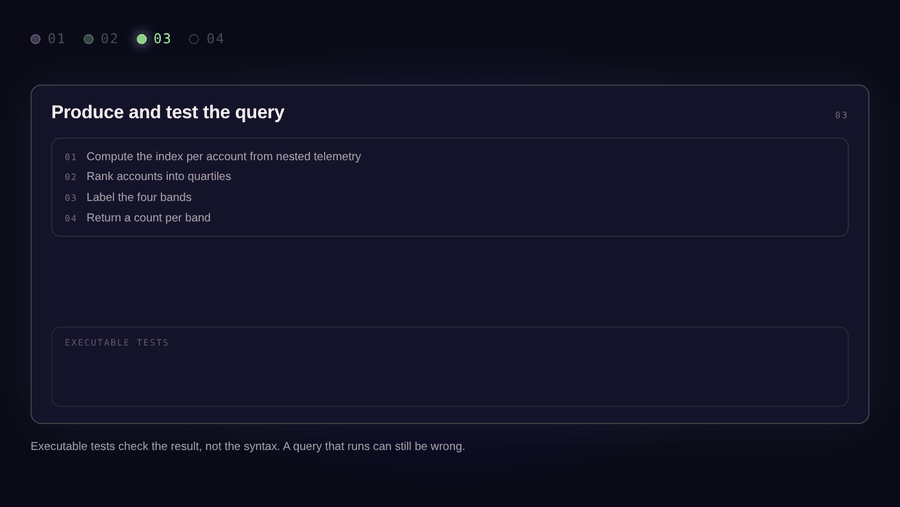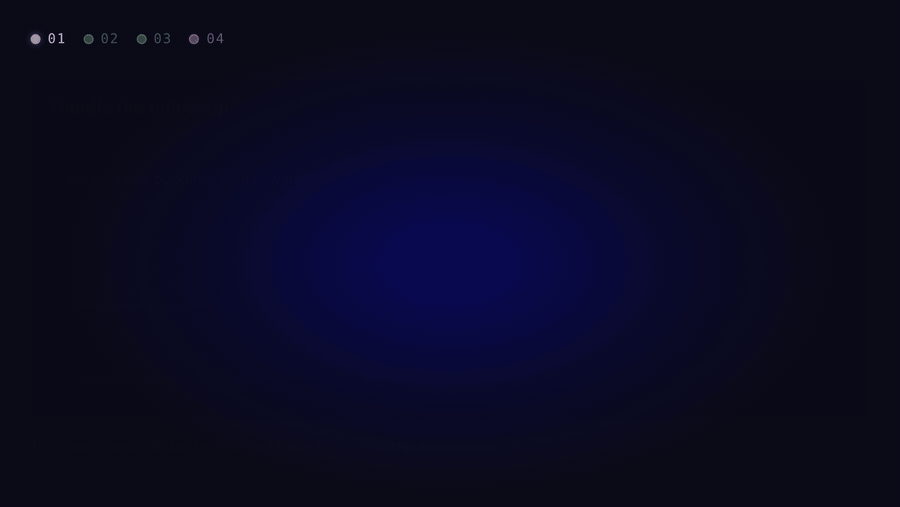
2. Clarify and explore.
The system can inspect database information, consult available knowledge, and ask the simulated user for clarification. Here, the evasion measure is a Technical Evasion Index (TEI), which is a composite of three signals buried in each account’s session telemetry. This definition is not in the knowledge base, so the system has to recognize the gap and ask. The danger zones are resolved separately as quartiles across the scored population, labeled from low to very high risk.
3. Produce and test the SQL.
The system must compute the TEI composite per account from nested telemetry fields, rank accounts into quartiles, label each band, and return a count per band. Executable tests check whether the result meets the task requirements. A query that runs without errors can still fail if it returns the wrong information.
4. Handle the follow-up.
The simulated user asks for the same bucketing applied to a different measure, the account’s overall security risk score. The method carries forward while the metric changes, and the system must transfer the quartile-and-label approach to a composite it has not yet computed.
What are BIRD-Interact’s two evaluation modes?
The interaction depends on the evaluation mode. In conversational mode (c-Interact), the system follows a predefined workflow. It can ask for clarification before submitting SQL, receives an opportunity to debug an unsuccessful solution, and moves to the follow-up once the initial task succeeds.
Agentic mode (a-Interact) gives the system more control over the sequence. It decides when to explore the database, consult documentation, ask questions, and submit SQL. Choosing the next useful action becomes part of the challenge.
What does a BIRD-Interact score mean?
Different BIRD-Interact scores describe different outcomes:
- Initial-task success: The percentage of tasks where the system completed the first request.
- Full-task success: The percentage of tasks where it completed both the first request and the follow-up.
- Normalized reward: A weighted score that gives credit for different levels of completion.
In agentic scoring, completing only the first phase earns 0.7; completing both earns 1.0. These rewards are averaged across tasks and reported on a 0–100 scale. A normalized reward of 21 therefore does not mean the system completed 21% of entire tasks. Conversational scoring also reduces the reward when a solution requires debugging.
| Neither phase completed | Phase 1 request only | Both phases completed |
|---|---|---|
| 0 points | 0.7 points | 1.0 point |
| ○ ○ | ● ○ | ● ● |
A reported score should identify the dataset, interaction mode (a-Interact or c-Interact), budget setting, and metric. Two numbers become useful to compare only when those evaluation conditions are clear.
What are bird-coins in BIRD-Interact?
Bird-coins are virtual units that measure the cost of an agent’s actions. In the agentic a-Interact setting, database exploration, clarification questions, and SQL submissions each carry a coin cost. Actions involving the simulated user cost more than database-only actions.
In Stress Mode, these actions draw from a per-task allowance stated in the model’s prompt. The agent must decide whether another lookup or clarification is worth spending its remaining coins. In Free Mode, no interaction budget is enforced, though coin use is still recorded. The leaderboard reports it as Efficiency, the total coins an agent spent on a task.
Bird-coins measure interaction cost, not correctness or dollar spending. Efficiency is reported in different units across modes: total bird-coins in a-Interact, conversational turns in c-Interact.
What will our results tell you?
BIRD-Interact tests abilities you would want in an assistant working with your own data: recognizing an unclear request, asking useful questions, finding the right information, and carrying context into a follow-up. Our evaluation asks how those abilities translate into task success when the system has access to an AtScale semantic layer.
Across the 410 business questions, Claude Sonnet 5’s phase 1 success rate rose from 25.9% to 56.6% in agentic mode under the stress budget. The other 190 are management operations that run against raw Postgres in both configurations, so the semantic layer plays no part in them. The ebook gives the full run methodology.
Note: This is a controlled evaluation using a simulated user and PostgreSQL databases. It provides evidence about performance on these tasks under the tested conditions. It does not establish how a system will perform on your data or at your scale. Results are preliminary and not yet verified by the BIRD team.
How does a semantic layer affect BIRD-Interact results?
Our BIRD-Interact evaluation examines how access to an AtScale semantic layer changes an AI system’s ability to answer business questions against a database. We compare performance with and without the layer to assess how shared business definitions and modeled relationships help the system interpret requests and produce correct answers.
Explore our BIRD-Interact results and ebook for the findings, evaluation methodology, and remaining limitations.
Resources to learn more
- BIRD-Interact project and leaderboard — Explore the benchmark, evaluation settings, and published results.
- BIRD-Interact research paper — Read the task design, scoring methodology, and original experiments.
- Code and evaluation setup — Find instructions for running evaluations and accessing the datasets.
- Full dataset — Browse the 600 tasks and their annotations.
- Original BIRD benchmark — Learn about the earlier text-to-SQL benchmark that provides context for this work.
- Dataset credit
- ICLR publication
Frequently Asked Questions about BIRD-Interact
Standard automated evaluations use a simulated user powered by a language model. It answers clarification questions using annotated task information and presents a follow-up after the phase 1 task succeeds. Executable tests check whether the submitted SQL meets the task requirements.
No. The full benchmark includes 410 business-intelligence tasks and 190 database-management tasks. These cover reading data as well as operations such as creating tables, updating records, and deleting data.
Success rate reports the percentage of tasks completed at a specified phase. Normalized reward gives weighted credit for progress. In agentic mode, completing only the phase 1 task earns 0.7 points; completing both phases earns 1.0. A normalized reward of 21 is therefore different from a 21% full-task success rate.
No. Bird-coins are virtual units that budget interactions in BIRD-Interact’s agentic stress mode. Actions consume coins from a task-specific allowance; they do not represent API charges or dollar spending.
No. A score describes performance on the benchmark under a particular configuration. It offers evidence about handling ambiguous requests and completing database tasks, but your data, business definitions, database platform, and operating conditions still require their own evaluation.
AtScale compares an AI system’s performance with and without access to a semantic layer. The evaluation examines how shared business definitions and data relationships affect task success. The BIRD-Interact results and ebook explain the findings, methodology, and limitations.